I still spend time re-routing #1234: a question filed as a bug, a feature pitch that should've been an Ideas thread, an install problem with no version in the body. Discussion category forms fix what shows up in the forum once someone lands there. This post is about policy and wiring: where contributors go first, and what happens when they open New issue anyway.
Some maintainers want questions, ideas, and suspected bugs in GitHub Discussions, triaged in public, with Issues opened only after the work is real. That takes five pieces: chooser routing, a reserved issue template, discussion forms (see How to Write Effective GitHub Discussion Templates for YAML and the Ideas and Community Help examples), CONTRIBUTING.md, and a pinned rules thread.
I'm wiring up community intake for an upcoming open source project. Issue forms and a pull request template were the easy parts. Community discussions were what I hadn't nailed yet.
I wanted a public place for questions and early ideas without Issues turning into a pile of one-liners. I've set up GitHub Discussions on other repos before; this time I wanted the same structured intake issue forms already give you.
So I used discussion category forms: YAML on the same schema as issue templates, with required fields, defaults, and labels on create, tied to a category instead of an issue chooser. Questions stay in the forum. Work that needs a tracker still opens an issue.
If you've shipped issue templates before, the field types won't surprise you. What's different is the plumbing: .github/DISCUSSION_TEMPLATE/, one YAML file per category, and a filename that must match the category slug—not bug.yml copied from Issues.
GitHub Container Registry ("GHCR") is GitHub's OCI-compatible container registry at ghcr.io. If your source code, releases, issues, permissions, and automation already live in GitHub, publishing container images to GHCR keeps the distribution path close to the repository that produced the image.
In this post, we'll publish a Docker image two ways: first manually from a local terminal, then automatically from GitHub Actions whenever a GitHub Release is published. Along the way, we'll cover image naming, authentication, permissions, release-driven tags, OCI labels, and the small details that make GHCR feel predictable instead of mysterious.
GHCR differs from a generic public registry when your project is already GitHub-centered:
Images can be associated with a repository.
Repository permissions can be used for package access.
GitHub Actions can publish with the built-in GITHUB_TOKEN.
Images can be public or private.
Tags, labels, and package metadata sit near the release and source history.
The registry supports standard Docker and OCI tooling.
Python packaging has needed a reset for years, and uv is the first tool in a long time that feels like a real one. It's fast, opinionated in the right places, and broad enough to replace an entire pile of Python tooling with a single binary that actually makes the day-to-day workflow simpler.
The official uv docs lead with the claim that it's 10-100x faster than pip, and that number doesn't feel like marketing fluff once you use it for real work. uv gets there by doing something the older Python toolchain never pulled together cleanly: it treats dependency resolution, environment management, Python installation, and tool execution as one system.
Most engineering teams still plan work in one tool and ship it in another. Issues live in Jira or Trello, pull requests live in GitHub, and every status change requires a human to copy context across tabs. GitHub Projects removes much of that friction by keeping planning, issue tracking, and delivery close to the code.
Current GitHub Projects is the planning layer on top of issues and pull requests: custom fields, saved views, built-in automations, roadmaps, charts, and API access. It replaces Projects (classic), not the same product with a new coat of paint.
For teams that already live in GitHub, the value is straightforward:
Less context switching between a tracker and the code host
Fewer stale status updates because issue and pull request state can drive project state
One place to plan cross-repository work without losing repository-level detail
A workflow that works for a two-person open source project, an inner source program, or a larger engineering org
Not Projects (classic)
This guide covers the current GitHub Projects experience. If you're starting fresh, use the new Projects workflow, not classic boards.
Mirroring a Git repository sounds simple until you need it to stay current without thinking about it. A one-time copy is easy. The useful version is a mirror that keeps following upstream branches, tags, and rewritten history without becoming another chore on your list.
I use this pattern for repositories I want to preserve, test against, or keep available under my own GitHub namespace. A recent r/github threasd asked about mirroring a public repository into a private one; this is the workflow I use for that and similar cases.
The twist is that I don't put the sync workflow in each destination repository. I keep the automation in a standalone private repository that acts as a mirror controller.
Before getting to GitHub Actions, it helps to understand the manual Git operation the workflow is automating.
A mirror is useful when you want a repository to follow another repository as closely as possible. That is different from a normal fork, where you expect to create your own branches, open pull requests, and maintain local work.
I usually think about mirrors as infrastructure, not collaboration space. They are useful for:
Keeping a personal copy of an upstream project
Preserving access to a dependency you rely on
Testing automation against a repository under your own namespace
Keeping several upstream repositories available from one GitHub account or organization
Avoiding a manual Sync fork habit for repositories that should simply track upstream
That last point is the practical one. If the destination is supposed to reflect upstream, humans should not be the scheduler.
Treat Mirrors as Destructive Targets
A mirror destination should not contain independent work. Mirroring usually involves forced updates to branches and tags, which means local-only changes in the destination can be overwritten. Use dedicated mirror repositories, not repositories where people are actively developing.
If most of the logs from your Go CLI still look like a wall of monochrome timestamps and free-form strings, you're leaving a lot of developer experience on the table. Charm's log package gives you colorful, readable, structured terminal output without forcing you into a heavyweight API or a machine-first JSON mindset from the start.
There's nothing wrong with simple logging. The problem is that simple logging tends to stay simple long after your application stops being simple.
At first, a few log.Println calls feel harmless. Then the output gets noisy. Errors look almost the same as info messages. Request context gets squeezed into ad hoc strings. The one line you need is somewhere in the middle of a hundred identical timestamps, and your terminal gives you very little help separating signal from noise.
That's the gap charmbracelet/log tries to fill. It's a leveled, structured, human-readable logger built for terminals. It looks good out of the box, keeps the API small, and still gives you the structured fields and formatting controls you want for real projects.
Two hours in, what you're actually shipping is a GitHub issue, a JIRA ticket, or a Slack thread: symptoms, hunches, pasted logs, then one more file because someone asked nicely. Each round trip tugs another detail out of your repo while the runnable version still lives mostly on your machine. Then a follow-up makes you spell out the repro steps you sort of skipped the first time, and halfway through your reply the bug stops looking fuzzy. Nobody merged a fix for you. You just finally described it clearly enough to see it yourself.
That loop is about as expensive as debugging gets, and almost none of it is mandatory. The antidote is the minimal reproducible example (MRE): the smallest, most self-contained piece of code that reliably triggers the problem you're trying to explain. Being kind to whoever reads your ticket is a nice side effect. The main payoff is that your own picture of the break gets sharper. Most of the time you'll see the answer yourself before you hit send.
Repositories that ship often, especially to GitHub Pages or similar environments, can rack up a long list of deployments. The UI is fine for spot checks, but it doesn't give you a fast way to clear old rows when you only care about what is current. The REST API deletes one deployment per request, so the practical approach is the same as workflow run cleanup: loop with the GitHub CLI (gh).
This post starts with a loop that deletes deployments whose latest status is inactive, then adds a variant that also removes error and failure without touching rows that still end in success.
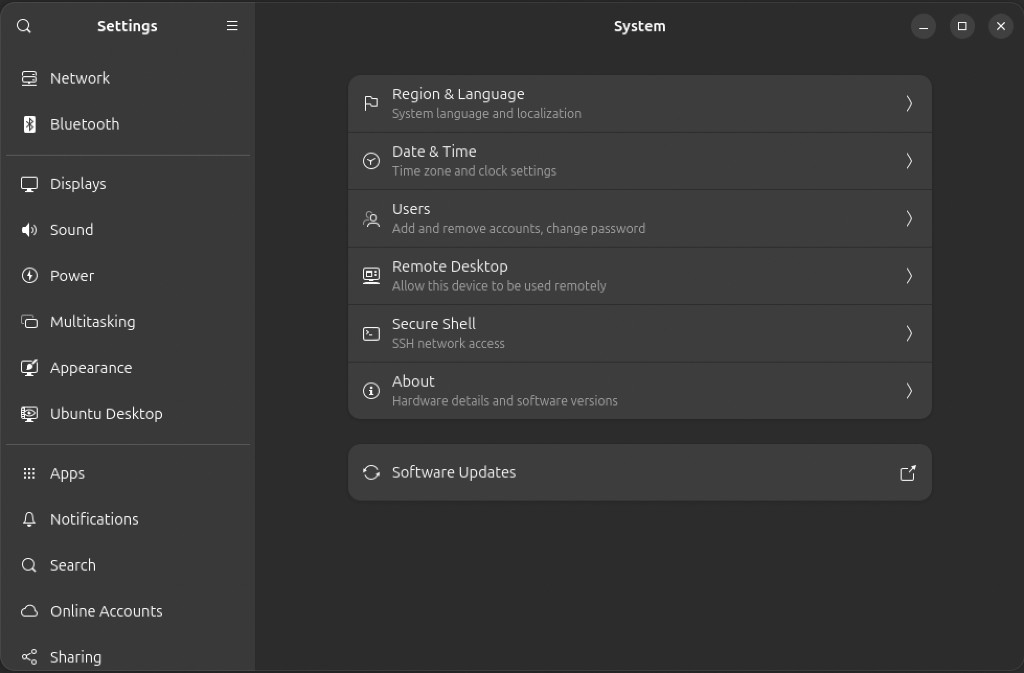
I still use RDP when I want a remote desktop on another machine. On Ubuntu 26.04 LTS Desktop (Resolute Raccoon, April 2026) the built-in path is Settings → System → Remote Desktop, matching what Canonical has documented since 24.04.
The steps below walk through the toggles, ufw, and how to connect with a client.
Desktop Sharing: View or control the desktop while you're logged in. Someone joins your live session. Resolution follows your local session, so the client can look a little soft.
Remote Login: Connect when the account isn't in use, closer to a headless workstation login. Resolution follows the client window, so it tends to look sharp. If you're already logged in locally, a remote user may get offered the nuclear option to end your session.
Tip
Generally, I use the Remote Login method.
Select the tab for the path you want.
Turn on the main toggle at the top of that tab.
Tip
You may need to click Unlock and enter your password before the toggle will stick.